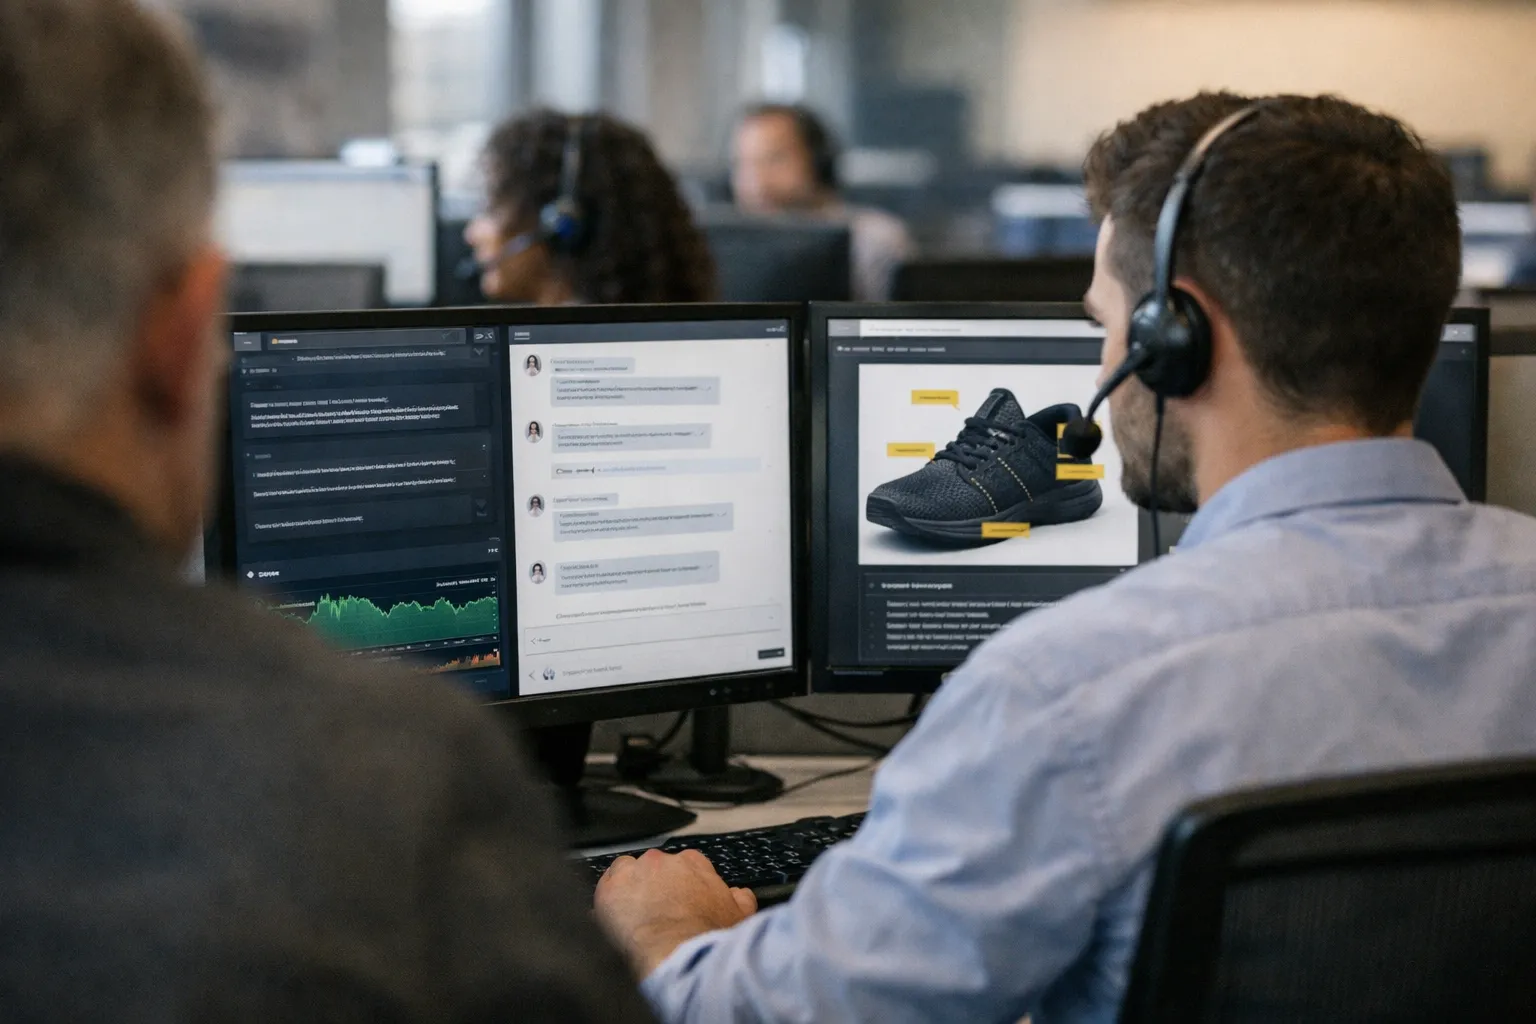
Contact centers are entering a new phase of automation as multimodal large language models (LLMs) — models that ingest and reason over text, speech and images — move from pilot projects into production agent-assist services. Vendors and enterprise buyers say the upgrades can reduce average handle time, surface document-level answers in real time and help agents resolve issues where visual context matters (for example, product photos or screenshots). But the deployments are also accelerating concerns about latency, data governance, auditability and regulatory compliance.
What’s changing: vision + speech + text in the agent workflow
Traditional agent-assist systems have relied on text-only LLMs and scripted knowledge bases. The new wave integrates vision-language models (VLMs) so that agents — and sometimes customers — can submit photos, screenshots or short video clips that the model analyzes inline while the agent is on the call or chat. Combined with live speech transcription, these systems can produce context-aware suggestions, step-by-step troubleshooting, proposed responses and forms pre-filled from visual evidence.
For example, an agent helping a customer with a warranty claim might receive an on-screen prompt that highlights damage in a submitted photo, suggests the warranty clause to cite and proposes the appropriate refund or replacement workflow. In another use case, agents handling billing disputes can upload invoice scans; the multimodal model extracts line items, flags inconsistencies and drafts a resolution script in near real time.
Business drivers
- Efficiency: Enterprises report lower average handle times and reduced escalations when agents get immediately relevant visual cues and suggested actions.
- First-contact resolution: Multimodal inputs help resolve cases that previously required follow-up because customers had to send images after the call.
- Agent enablement: Visual context reduces reliance on subject-matter experts and shortens ramp-up time for new hires.
How vendors are packaging multimodal assist
Contact-center platform providers are integrating multimodal models in two primary ways: hosted cloud inference and hybrid on-prem/edge options. Hosted services emphasize continuous model updates and rich multimodal features, while hybrid offerings aim to keep sensitive images and transcripts on customer-managed infrastructure to address privacy and compliance requirements.
Vendors are also layering specialized pre- and post-processing: automated image redaction, OCR tuned for invoices and receipts, and tighter similarity scoring for document retrieval. Several providers now offer “assist confidence” scores so supervisors and compliance teams can filter which agent suggestions are surfaced automatically and which require agent confirmation.
Operational and compliance trade-offs
While the productivity benefits are clear, enterprises face several non-trivial operational challenges when rolling out multimodal LLMs:
- Latency and reliability — Real-time multimodal inference is compute-intensive. Achieving low-latency responses without sacrificing accuracy requires caching, model distillation or edge inference nodes colocated with contact-center clusters.
- Data governance — Images and video can contain personally identifiable information (PII) or sensitive corporate data. Firms must define retention policies, implement selective redaction and ensure encryption both at rest and in transit.
- Auditability — Regulators and internal risk teams often require explainable trails for automated assistance. Multimodal models complicate provenance: teams must log inputs, intermediate model states (where feasible), and the exact model versions and weights that produced an assist.
- Bias and false positives — Vision models can mislabel or misinterpret images (for instance, misidentifying product damage). Contact centers need human-in-the-loop controls and incident review processes to catch and remediate systematic errors.
Early adopters and pilots
Large retailers, consumer electronics manufacturers and utilities are among the early enterprise adopters. These companies cite reductions in escalation rates and improvements in customer satisfaction for image-heavy support scenarios such as returns, installation issues and field-service troubleshooting.
Implementation patterns vary. Some enterprises pilot with limited agent groups and narrow use cases (e.g., invoice OCR plus human review), while others integrate multimodal assists across voice, chat and video channels. A common best practice emerging from pilots is progressive rollout with strict guardrails: begin with read-only visual analysis, then expand to suggestive assists, and finally allow auto-population of forms with supervisory oversight.
What IT and procurement teams should ask
Enterprises evaluating multimodal contact-center deployments should probe vendors on several practical items:
- Model provenance and versioning: Can the vendor provide immutable records of the model version used to generate each assist?
- Data handling and retention: How are uploaded images, video and transcripts stored, redacted and deleted?
- Latency SLAs and fallback behavior: What is the latency under peak load and what happens when inference fails?
- Monitoring and KPIs: What observability exists for model drift, assist accuracy, and user feedback loops?
- Compliance readiness: Does the solution provide features to comply with sector-specific requirements (financial services, healthcare, telecom)?
Looking ahead
Multimodal LLMs are poised to become a standard component of modern contact centers where visual context is relevant. But the pace of deployment will depend on how quickly vendors and customers solve the operational problems around latency, auditability and data governance. As momentum grows, expect to see more packaged compliance templates, hardened inference appliances for regulated industries, and tighter integrations between contact-center analytics and model observability stacks.
For AI-for-business leaders, the central question is not whether multimodal assist will improve agent performance — evidence increasingly suggests that it will — but whether their organizations can build the governance, monitoring and incident-response practices required to scale it responsibly.