As enterprises push more large language models (LLMs) and retrieval-augmented generation (RAG) systems into production, observability has become an operational necessity. This August 2026 update evaluates Arize AI’s observability platform for model-ops teams: what’s new since May 2026, real-world signals from live pilots, practical trade-offs, and an actionable pilot plan that limits telemetry spend while proving value quickly.
Overview — What are we reviewing? Key specs at a glance
- Product: Arize AI observability platform (SaaS with hybrid ingestion and on-prem options)
- Primary focus: Telemetry ingestion (prompts, responses, embeddings, labels, metadata), drift & anomaly detection, RAG diagnostics, root-cause tooling, explainability for generative outputs
- Integrations: Kafka, S3/Blob, Snowflake, major vector DBs (Pinecone, Milvus, RedisVector), orchestration tools (Airflow, Dagster), model registries, and SDKs for Python/Go plus webhook/alert integrations
- Target audience: Mid-to-large enterprises running production LLMs, RAG systems, and regulated language applications
Background — Who makes this and who's it for
Arize AI began as a telemetry-first model observability vendor and has iterated toward LLM- and retrieval-specific use cases. By 2026 the company sits at the center of many production stacks as the place teams route telemetry to understand retrieval quality, embedding drift, token-level anomalies and hallucination vectors. If your business depends on retrieval fidelity, regulated text outputs, or multi-tenant chat services, Arize is built to surface operational signals across hosted and self-hosted models.
Features analysis — Deep dive into capabilities (what changed)
Since May 2026 the market emphasis shifted from purely surfacing signals to helping teams reduce telemetry costs and close the remediation loop. The key practical updates and capabilities observed in customer pilots:
- Cost-aware ingestion patterns: More teams use Arize’s hybrid ingestion templates: aggregated embeddings for broad telemetry, adaptive token sampling guided by anomaly detectors, and on-demand high-fidelity traces for labeled cohorts. This reduces storage and ongoing bill shock.
- Embedding retention tiers and compression: Vendors and vector stores pushed storage techniques — quantization, chunked retention, and client-side PCA — so teams now routinely keep centroids and sparse vectors for 90–180 days and unreduced vectors only for hot cohorts.
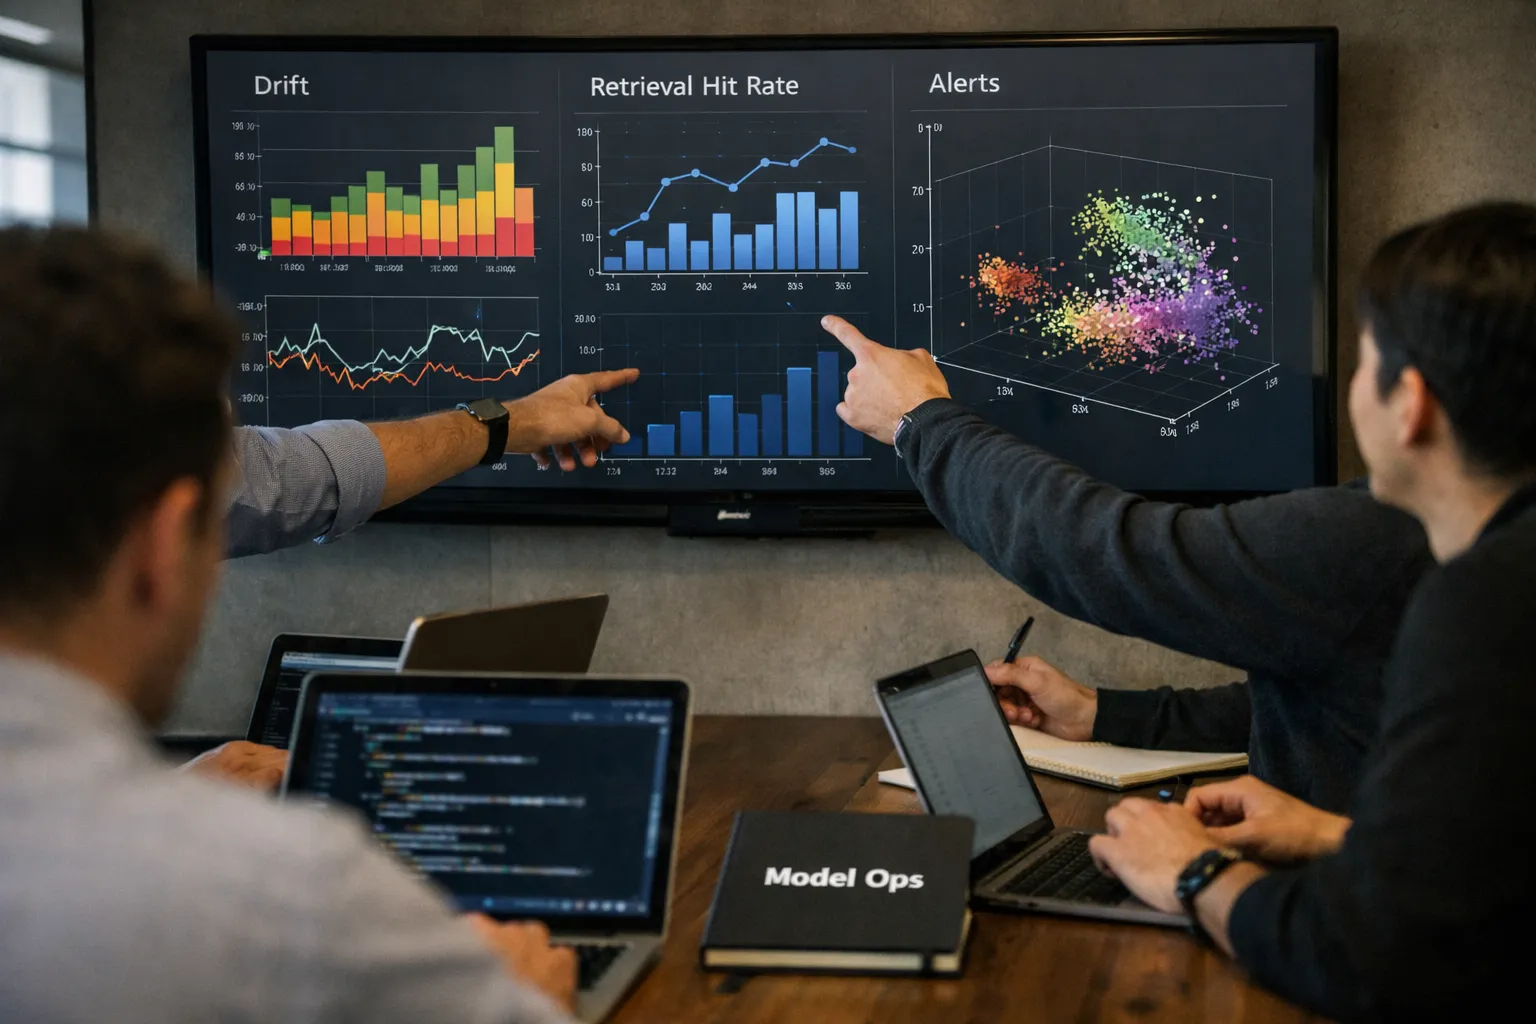
- RAG provenance and hit-rate correlation: Arize’s retrieval diagnostics now emphasize correlating top-K hit rates, provenance scores, and refresh cadence with downstream hallucination metrics. Practical outcome: teams detect stale index windows (e.g., missed daily ETL) that spike hallucinations for specific cohorts.
- Explainability focused on hallucination signals: Token- and sequence-level anomaly scoring is paired with provenance heatmaps and counterfactual prompts. These improve triage speed but still depend on labeled examples to attribute root cause reliably.
- Operational playbooks and runbooks: More prebuilt alert-to-remediation templates ship in the platform (index refresh, fallback prompt swap, rollbacks). Customers still customize these with orchestration systems to attain safe automation.
- Security and data residency options: Arize customers report tighter controls: field-level redaction, encrypted-at-rest ingestion, and clearer routing patterns for EU/UK data residency. Expect legal and infra reviews on pilots in regulated sectors.
Pros and Cons — Balanced assessment with specifics
- Pros:
- RAG-first diagnostics that expose specific vector-store and ingestion failures — crucial when business outcomes depend on retrieval quality.
- Flexible ingestion (streaming + batch + SDK) with sampling templates reduces cost while keeping signal quality.
- Actionable triage views (cohort slicing, provenance heatmaps) that speed cross-functional handoffs between SRE, ML, and product teams.
- Cons:
- Token-level tracing is still expensive; expect to trade fidelity for coverage unless you design a sampling strategy.
- Automated remediation remains largely customer-implemented — Arize provides alerts and templates, not guaranteed one-click fixes.
- Good signals require investment: telemetry schema design, labeling pipelines, and clear retention policies.
Pricing / Value — control costs and prove ROI
Arize continues with usage-based billing—metering telemetry volume, embedding storage, and retention. Practical guidance drawn from 2026 pilots:
- Start with a tightly scoped pilot: sample prompts for two high-risk workflows, ingest aggregated embeddings for product-wide monitoring, and keep unreduced vectors for a 1–2% labeled validation cohort.
- Define billing guardrails: set daily ingestion caps, configure automated down-sampling, and negotiate committed-volume discounts if your telemetry is predictable.
- Estimate pilot spend conservatively: many organizations run 30–60 day pilots for $5k–25k depending on telemetry rate and retention choices; production scale varies widely and should be modeled by telemetry per active session rather than user count.
Integration and deployment notes — practical steps
- Design telemetry deliberately: Map risks to telemetry: customer-facing outputs, regulated domains, high-value SKUs. Don’t skip schema discipline—consistent keys enable reliable cohorting.
- Use adaptive sampling: Configure baseline aggregation, then enable high-frequency traces only when anomaly detectors or labelers mark a cohort as suspicious.
- Wire alerts into actions: Route Arize alerts to incident channels and one-off remediation jobs (index-refresh, fallback prompts). Prototype one automated remediation (e.g., index-refresh job triggered by low provenance + high hallucination signal) before trusting it in production.
Kitchen-style tip: treat telemetry like seasoning — start with the essentials for safety and compliance, then add finer-grain traces as you taste what the signals reveal. Don’t dump token traces into production without a plan for retention and labeling.
Who it's for — use cases and ideal customers
- Best fit: Mid-to-large enterprises operating production LLMs and RAG at scale where retrieval quality, auditability, and cross-team triage matter (finance, healthcare, legal, e‑commerce, telecom).
- Consider with caution: Early-stage startups with tight budgets — open-source stacks or minimal custom telemetry are cheaper but require engineering trade-offs.
- Not ideal: Teams seeking drop-in fully automated remediation without investing in orchestration, labeling, and governance.
Alternatives — short list
- Open-source observability stacks + custom telemetry (Prometheus, custom vector metrics) — lower cost but higher engineering burden.
- Integrated MLOps suites (Databricks, Sagemaker Ops-style offerings) — can offer tighter remediation but may be more opinionated and less vendor neutral.
- Vector DB-specific monitoring tools — good when retrieval is the only concern, but limited for end-to-end prediction-to-label observability.
Practical examples — new August 2026 cases
- Telecom customer support bot: A large carrier used sampling + retrieval diagnostics to catch a nightly ETL failure that removed recently launched plans from the index. Fixing the ETL and switching to a quick fallback prompt reduced misrouted billing complaints by 70% within 24 hours.
- Pharma adverse-event triage: A pharmacovigilance team combined provenance scoring with labeled audits to reduce false-positive adverse-event flags caused by ambiguous synonyms. The observability pipeline cut manual review hours by 40% while improving precision on flagged cases.
Verdict — who wins with Arize in August 2026?
Arize remains a strong choice for enterprises that will invest in telemetry design and labeling discipline. The platform’s RAG and embedding diagnostics are increasingly practical because teams have adopted cost-aware ingestion patterns and automation templates. Arize surfaces useful signals quickly, but success still hinges on governance: sampling strategy, retention policies, and an operational playbook that ties alerts to safe remediation.
Actionable next steps
- Run a 30–60 day pilot using sampled prompts for two high-risk flows and aggregated embeddings across products; keep a 1–2% labeled holdout for high-fidelity traces.
- Define billing guardrails, retention windows, and down-sampling thresholds before you start ingesting token traces.
- Integrate one automated remediation: prototype index-refresh or fallback prompt swap using your orchestration tooling to close the loop on one alert type.
FAQ — common questions teams ask
How much telemetry should I send on day one?
Start with risk-focused telemetry: log prompts/responses for your highest-risk flows, aggregated embeddings for broad coverage, and full token/embedding traces only for a small labeled validation subset. Set daily ingestion caps and a retention policy. This reduces cost and delivers actionable signals quickly.
Will Arize fix hallucinations automatically?
No. Arize surfaces probable causes—stale retrievals, distributional shifts, prompt changes—and provides remediation templates. Automated fixes require you to wire alerts into orchestration systems that perform index refreshes, fallback routing, or safe rollbacks and to build proper guardrails for those actions.
Can Arize meet strict data residency and compliance needs?
Arize supports enterprise controls (field-level redaction, encrypted ingestion, regional routing) but compliance depends on contract terms and your architecture. Engage your security, legal, and infra teams early when planning a pilot in regulated sectors.
What are the most common onboarding pitfalls?
The two frequent problems are: (1) ingesting too much raw telemetry without retention rules, which inflates costs; and (2) lacking labeled data for high-risk cohorts, which makes drift signals noisy and hard to act on. Plan sampling, labeling, and playbooks up front.
What measurable outcomes should I expect from a 60-day pilot?
Practical pilot goals: validate that Arize alerts correlate with known incidents (precision > 60–70% on your labeled holdout), reduce time-to-detection for key failure modes (target 2–4x improvement), and demonstrate one remediation that shortens mean-time-to-repair (MTTR) for a defined cohort.