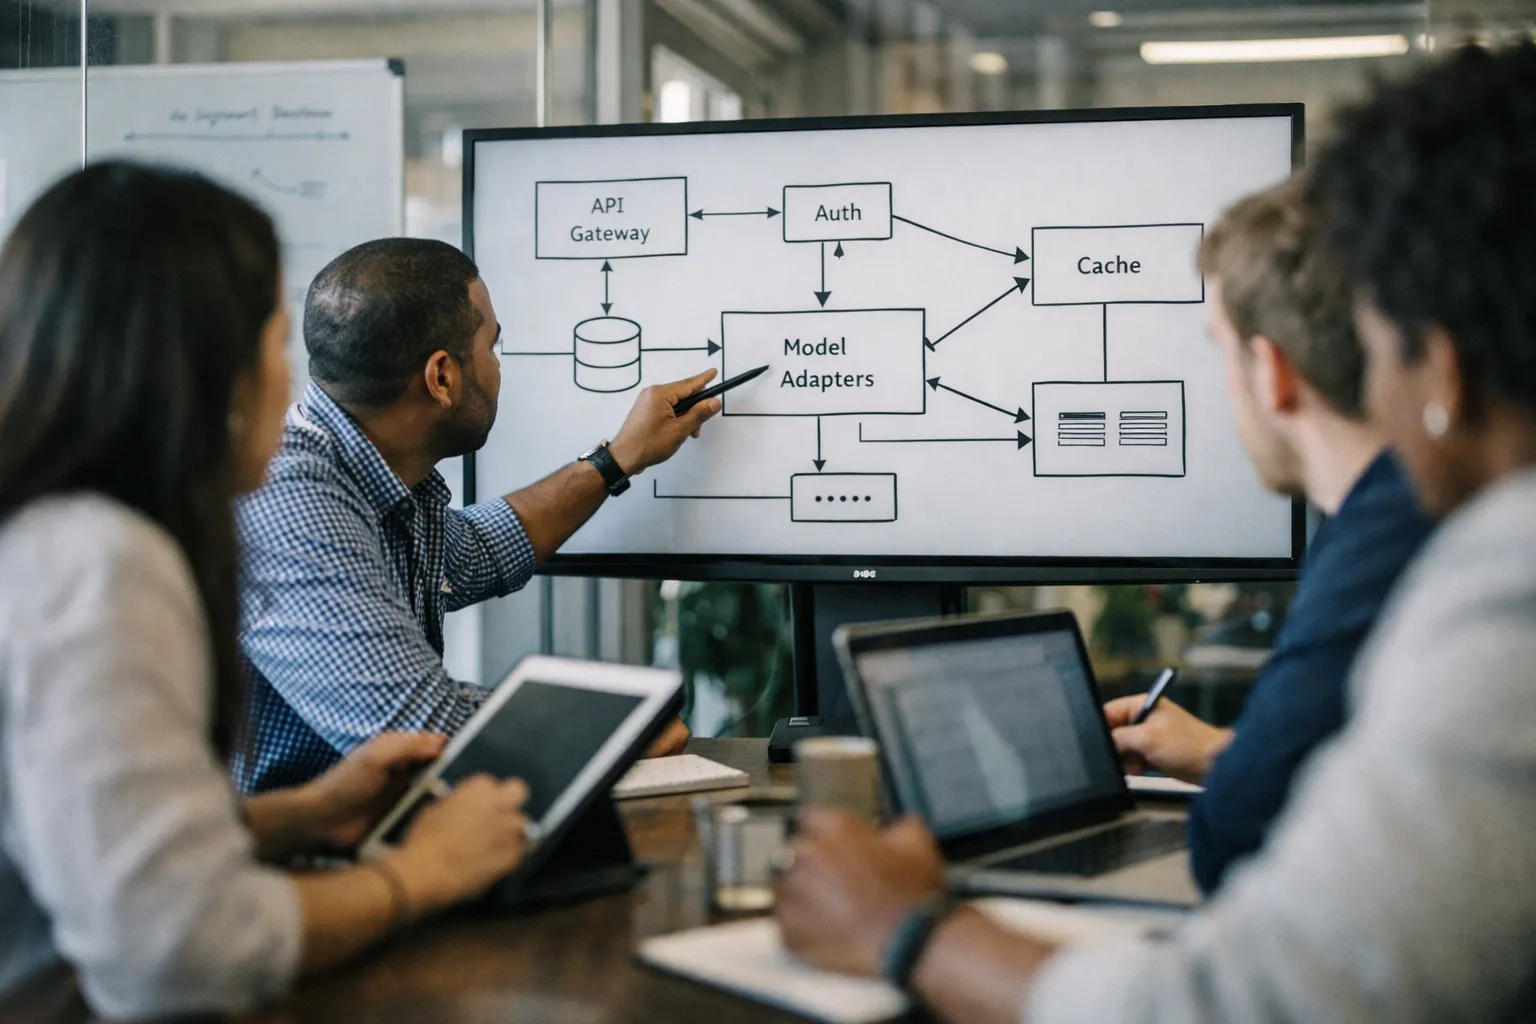
Enterprises deploying large language models (LLMs) in production increasingly need a centralized control plane — an LLM query gateway — that enforces security, cost controls, and operational observability. This guide walks AI-for-business teams step-by-step through designing, building, and operating a gateway that sits between applications and model providers (public APIs, private models, or hybrid deployments).
Why a dedicated LLM query gateway?
Direct app-to-model connections create problems at scale: runaway consumption bills, inconsistent prompt handling, insufficient audit trails, and uncontrolled data leakage. A purpose-built gateway addresses these by centralizing:
- Authentication and tenant routing (who can call which model).
- Cost controls and quotas (per team, product, or environment).
- Prompt templating and guardrails to reduce hallucination and PII exposure.
- Caching and deduplication to eliminate redundant requests.
- Observability and attribution for chargeback and SLOs.
High-level architecture
At its core the gateway is a stateless HTTP layer with tightly integrated state services. Typical components:
- API ingress (Envoy/Kong/API Gateway).
- Auth & tenant service (OAuth/OIDC, JWT validation).
- Policy engine (rate limits, token budget, prompt policies).
- Routing & model adapters (map logical model keys to endpoints).
- Cache & dedup store (Redis/Velero) and short‑term persistent store.
- Audit and telemetry pipeline (OpenTelemetry → Kafka → Prometheus/Grafana/SIEM).
- Secrets & key management (HashiCorp Vault, cloud KMS).
Deploy the gateway either as a Kubernetes service (best for control and extensibility) or as a serverless function fronted by API Gateway for lighter operations.
Step 1 — Define objectives and policies
Before building, document clear objectives and policies that the gateway will enforce. Minimum items:
- Authorization model: tenant, team, role, environment (prod/non‑prod).
- Cost policy: per-tenant daily/weekly budgets, per-request token limits, off-peak vs peak prioritization.
- Data handling: allowed input, redaction rules, persistence & retention.
- Response rules: max latency SLOs, fallbacks to cached or lower-cost models.
- Audit policy: what to log (metadata only vs full payload) and retention period.
Step 2 — Implement authentication & tenant routing
Authentication and tenant identification are the gateway’s first responsibility:
- Use OAuth2/OIDC for user and service identity. Require JWTs with tenant and role claims.
- Validate tokens at the gateway layer and enforce scopes (e.g., "llm:invoke:summary").
- Map tenant claims to routing rules and quotas. Maintain a tenant config store (Postgres or a managed config DB) with budgets and model permissions.
Tip: keep auth validation fast—cache public keys and token introspection results for short TTLs to avoid added latency.
Step 3 — Centralize prompt templates, guardrails, and data redaction
Inconsistent prompts produce inconsistent outputs and unpredictable costs. Centralize prompt management:
- Store canonical prompt templates and parameter schemas. Enforce schema validation at the gateway using JSON Schema or Protobuf.
- Implement pre-send transformations: truncate or summarize long user input, remove or redact sensitive fields, and enforce token budgets at the prompt level.
- Insert system-level instructions to enforce company policy (e.g., "Never provide legal advice; refer to legal team").
Combine guardrails with a “dry-run” policy mode during rollout to measure impact before fully enforcing changes.
Step 4 — Token budgeting, request shaping, and cost control
Most enterprise cost surprises come from high token consumption. Mitigate with these controls:
- Per-request caps: enforce max input and output tokens.
- Per-tenant budgets: daily/weekly budgets with hard and soft limits (soft = throttling warning; hard = block or redirect).
- Rate limiting and concurrency controls to prevent spikes.
- Request shaping: for expensive tasks, offer lower-cost alternatives automatically (e.g., reroute to cheaper model or cached answer).
Implement counters in Redis or a time-series DB for precise budget tracking. Emit budget events to alerting systems when thresholds approach.
Step 5 — Caching, deduplication and response reuse
Caching is the single most effective way to reduce inference spend for repeatable queries.
- Deterministic cache: hash canonicalized prompt + model + model params; cache responses for N minutes/hours based on freshness requirements.
- Semantic deduplication: use embeddings (local or vector DB) to detect near-duplicates and reuse results when similarity > threshold.
- Stale-while-revalidate: serve cached response while refreshing in the background for low-latency UX.
Decide TTLs by use case: knowledge-based Q&A may allow long TTLs; personalized generation typically needs shorter caching or none.
Step 6 — Model routing, adapters, and fallbacks
Support a portfolio of models: public APIs, private fine-tuned models, and on-premises instances. Build an adapter layer that maps logical model names to endpoints and configurations.
- Routing rules: route by tenant, task type, cost profile, latency SLO.
- Fallback strategy: on timeout or error, fallback to a cheaper or local model, degrade gracefully, or return a cached response.
- Canary & staged rollout: support traffic splitting to test new models or providers safely.
Step 7 — Observability and chargeback
Observability must capture both operational and financial signals:
- Trace each request: include tenant, model, token usage, latency, and cache hit/miss.
- Aggregate token usage and cost estimates per tenant, team, and product for chargeback reports.
- Set SLOs and alerts: request latency P95/P99, error rates, budget burn rate.
- Instrument with OpenTelemetry; route metrics to Prometheus/Grafana and logs to a centralized store or SIEM.
Important: do not log raw user content without explicit policy approval—log metadata and security hashes instead.
Step 8 — Secrets, keys, and compliance
Protect provider API keys and any decrypted user data:
- Use Vault or cloud KMS to store keys and rotate them regularly.
- Encrypt sensitive payloads in transit and at rest.
- Implement data residency controls: route EU customer data to EU-hosted models or on-premise deployments if required.
- Maintain audit trails for compliance reviews and incident response.
Step 9 — Testing, canarying and rollout
Follow a disciplined rollout:
- Unit and integration tests for policy enforcement and fallback flows.
- Load/stress tests to validate quota enforcement under burst conditions.
- Canary releases: route a small % of prod traffic through the gateway and monitor cost, latency, and error signals.
- Enable a “policy dry-run” to collect telemetry without blocking requests before enforcement.
Operational playbook and runbook examples
Prepare runbooks for common incidents:
- Runaway cost: steps to suspend non‑critical tenants, switch traffic to cached or cheaper models, and alert finance.
- Provider outage: automatic failover to alternate provider or local model adapter.
- Data leak suspicion: immediate token revocation, log freeze, and forensic extraction from audit logs.
Deployment patterns and scaling
Choose a deployment pattern that matches organizational needs:
- Kubernetes: recommended for complex multi-tenant environments requiring autoscaling, custom adapters, and fine-grained control.
- Serverless: appropriate for smaller teams or low-traffic gateways wanting minimal ops.
- Hybrid: gateway control plane in k8s with heavy inference routed to managed providers or on-prem GPU clusters.
Checklist for a production-ready gateway
Before declaring the gateway production-ready, verify:
- Auth & tenant routing validated with integration tests.
- Budget enforcement and alerting configured and tested.
- Prompt templates and redaction policies in place.
- Caching and deduplication producing measurable cost reduction in UAT.
- Observability and chargeback reporting validated against sample billing.
- Runbooks for cost spikes, provider outages, and suspected data leaks created and tested.
Real-world considerations and examples (2026)
By late 2026, many enterprises run mixed-provider landscapes: a mix of proprietary foundation models, cloud APIs, and specialized on-prem models for regulated workloads. Common patterns we observe:
- Finance teams prefer hard budget caps with automated fallback to cheaper models during end-of-quarter spikes.
- Customer support uses cached responses and semantic deduplication to reduce repeat calls for similar tickets.
- Legal and HR require strict prompt templates and redaction pipelines to prevent PII leakage into public provider logs.
These practices align with the gateway approach and emphasize the need for central policy enforcement rather than ad-hoc controls embedded in each application.
Emerging features to plan for
Plan your gateway roadmap to incorporate:
- Fine-grained cost-aware routing (dynamic model selection by real-time price/latency tradeoffs).
- Automated prompt optimization (shortening or restructuring prompts to meet token budgets without losing downstream quality).
- Runtime model explainability hooks (traceability of which prompt fragments influenced output) for auditability.
Conclusion
An LLM query gateway is an essential control plane for any enterprise using LLMs at scale. It centralizes security, cost control, and operational observability while enabling safe, auditable access to a growing mix of model providers. Start small: implement auth, quotas, and caching first, then incrementally add routing, guardrails, and chargeback. With a sound gateway in place, AI teams can accelerate business use cases with predictable costs and stronger governance.